Blog
Keep updating with our latest articles
Insights on building AI-native products, shipping fast, and scaling startups with intelligence built in from day one.
An agent eval needs a release contract, not a score
A useful agent evaluation defines the scenario, grades the outcome and execution trace, enforces operating limits, and blocks releases on regressions.
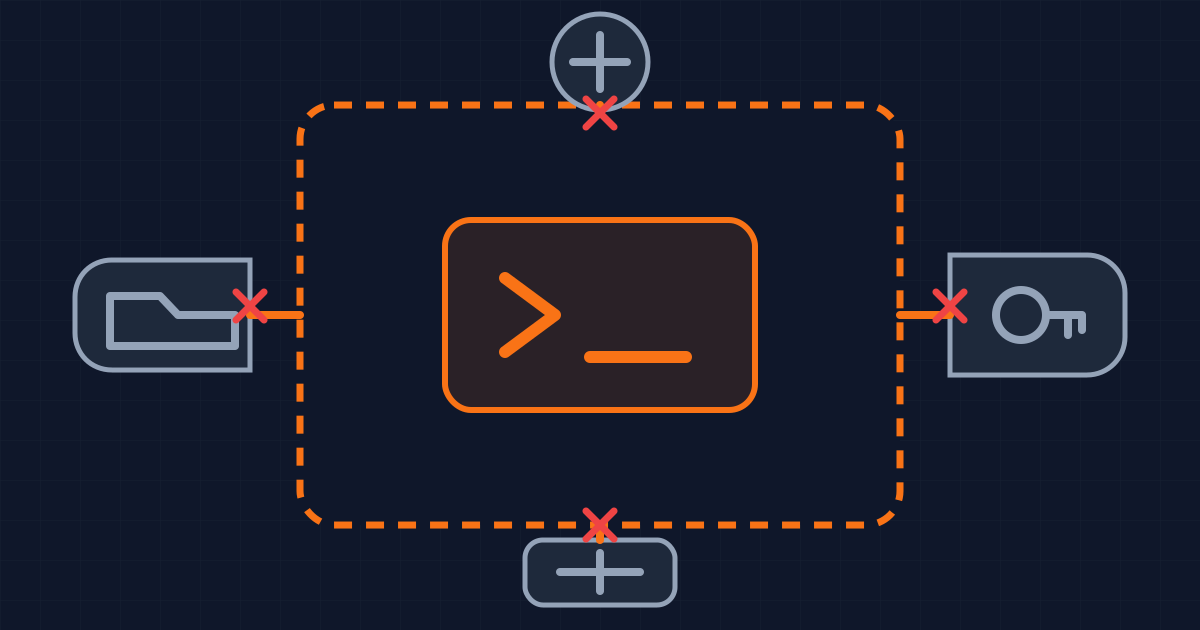
Copilot's local sandbox is a policy, not a safe mode
GitHub Copilot can now constrain agent-run commands on a developer machine. The useful boundary depends on explicit filesystem, network, credential and subprocess policy.
Prompt caching is a serialization contract
Prompt caching only works when your application preserves a reusable prefix. How to design that boundary, measure it, and keep tenant data separate.
Jev Brings Typed Decisions to AI Workflows
TypeSafe's Jev returns structured decisions instead of generated text. Where it fits in an agent workflow, what confidence means, and what still belongs in your code.
GPT-6 Astra Makes Long Agent Runs Interruptible
Astra adds mid-turn steering, asynchronous tool calls and persistent WebSocket sessions. The useful change is operational: long agent runs can accept corrections without throwing away their state.
Subscribe to our newsletter to receive research and other information about the industry and what we do.